
Equipment Condition Monitoring for OEM Vehicle Manufacturing
Automotive original equipment manufacturers (OEMs) depend on presses, conveyors, robotic welding cells, paint-shop equipment, assembly fixtures, pumps, compressors, and other production assets to keep vehicle manufacturing on schedule. A developing equipment problem can affect cycle time, product quality, line availability, and downstream workstations. Equipment condition monitoring uses relevant machine measurements and operating records to help teams recognize changes, investigate abnormal behavior, and prioritize maintenance review.
Contact OEMNex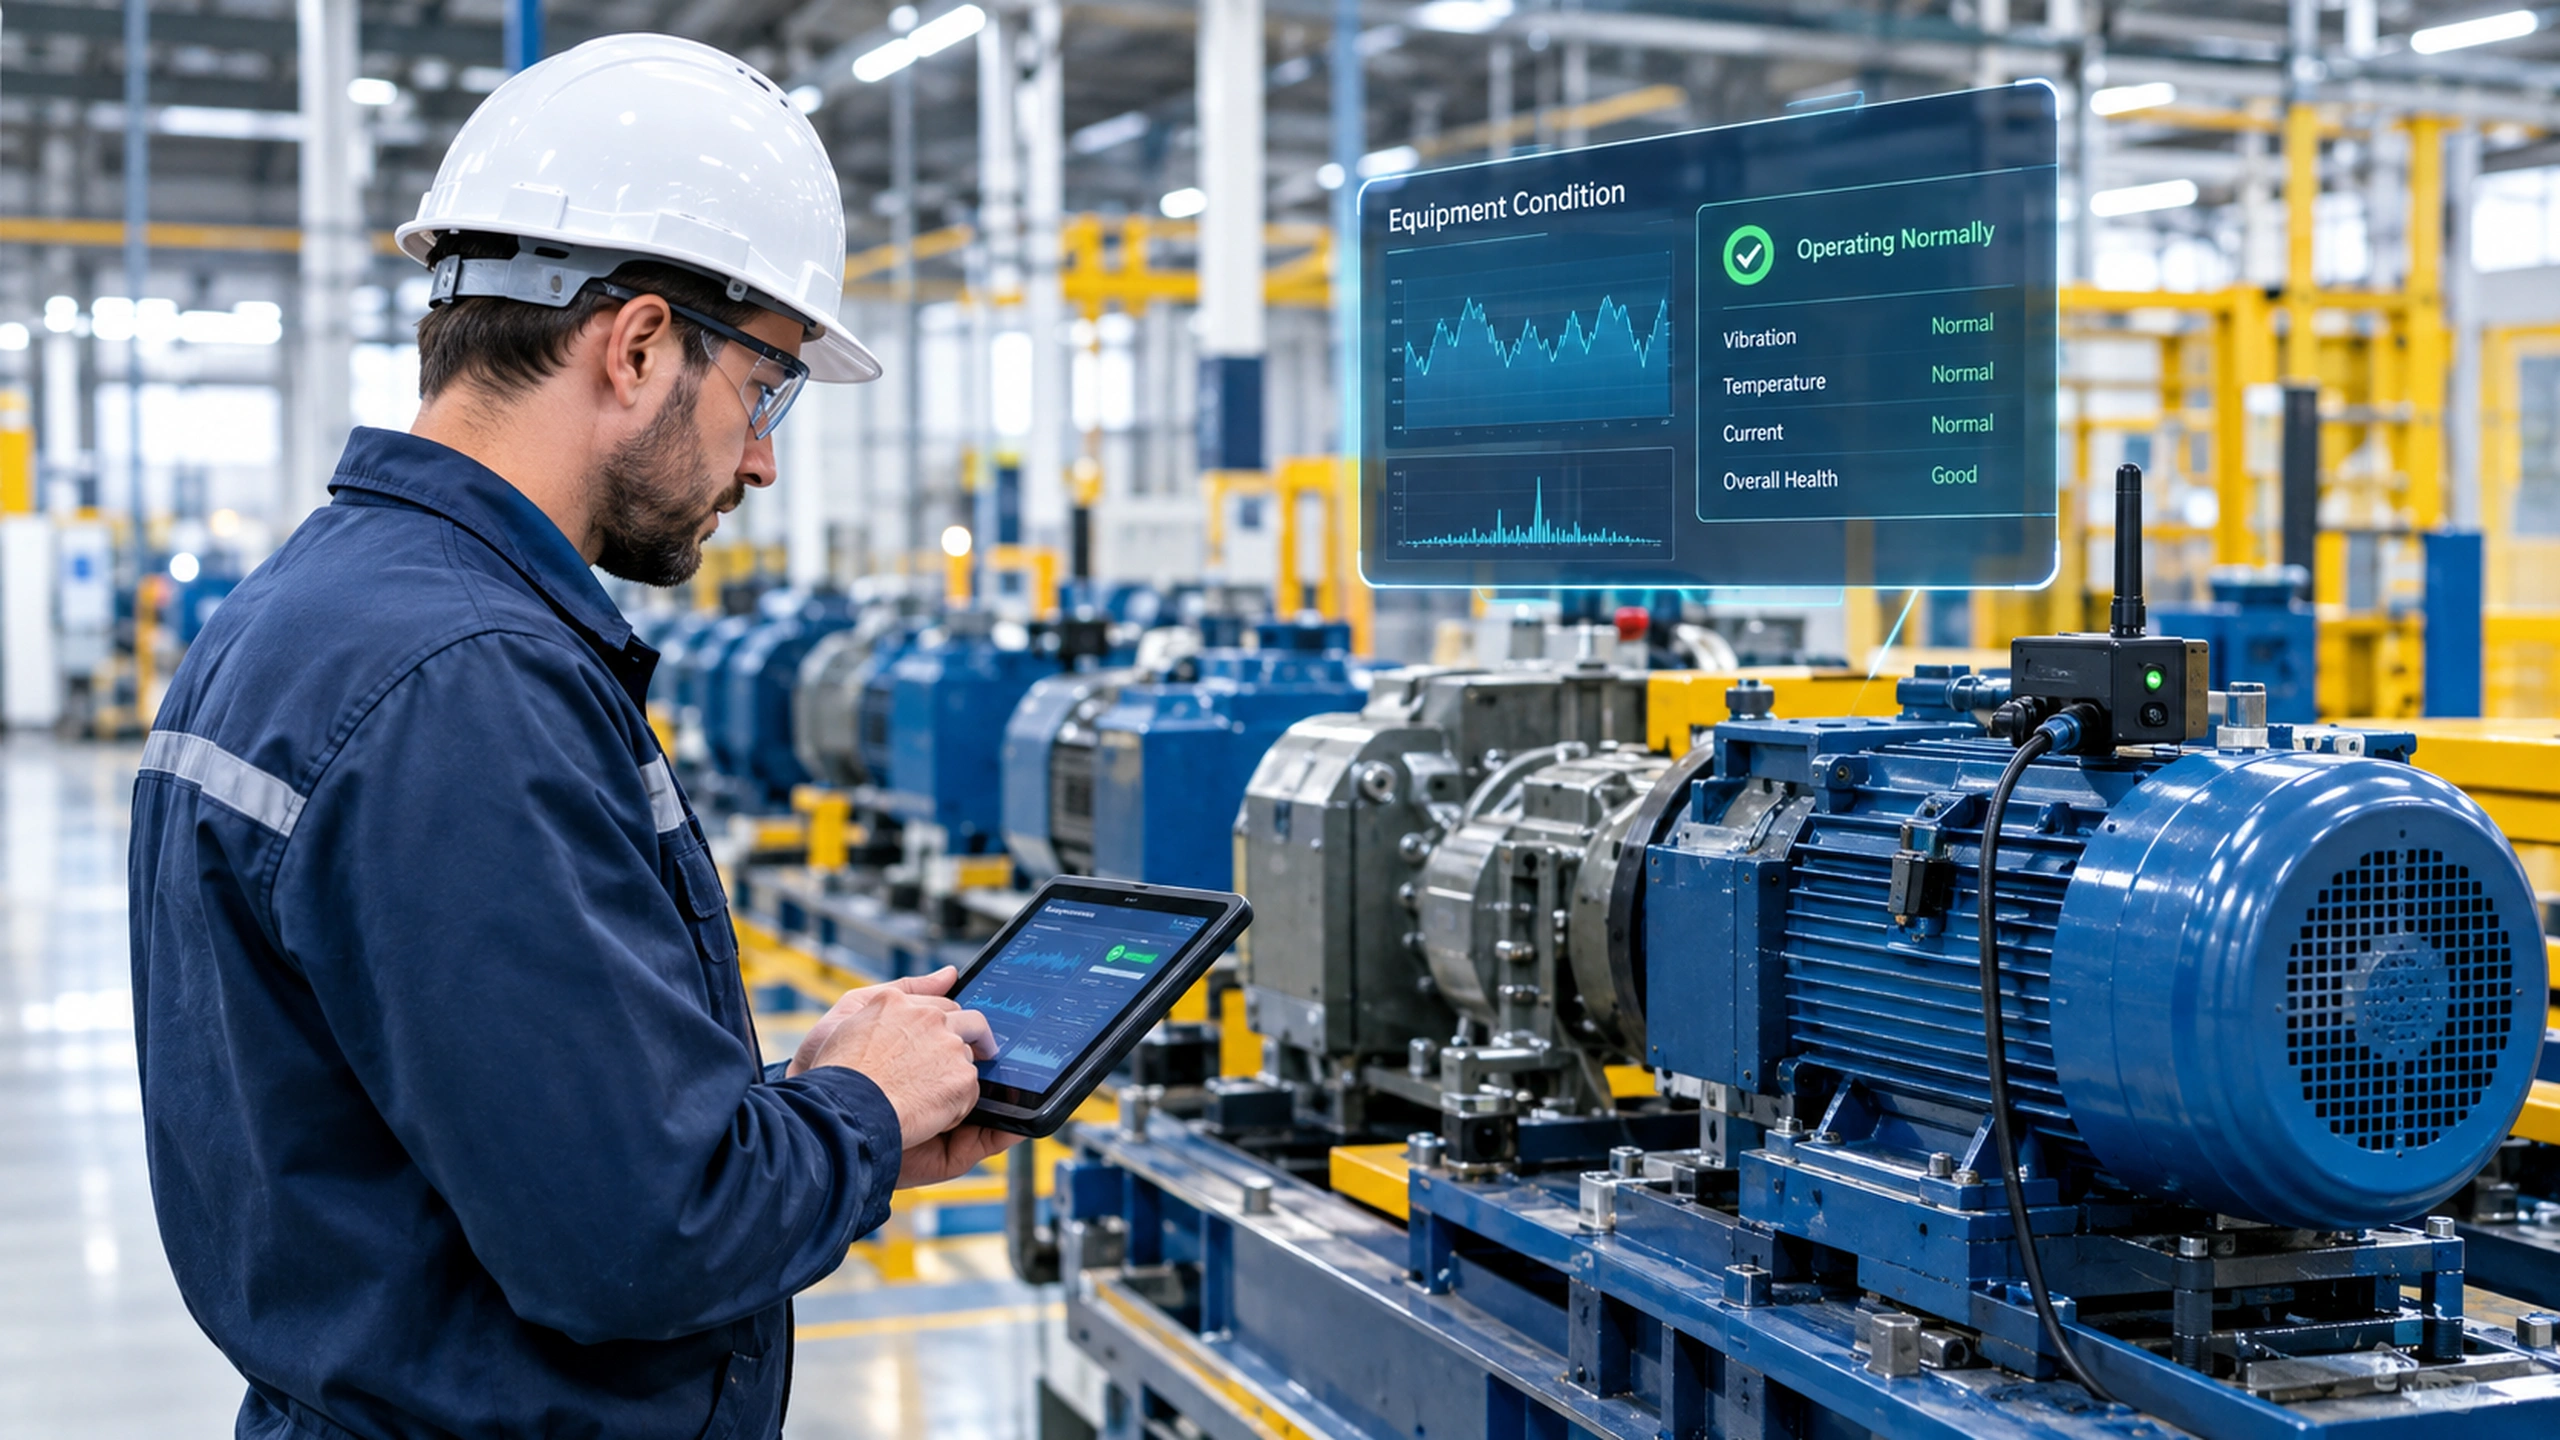
OEMNex focuses on Physical AI and Artificial Intelligence of Things (AIoT) applications for OEM vehicle manufacturing. A condition-monitoring workflow can connect equipment identity, measurements, operating context, AI-supported analysis, and maintenance records. The right design depends on the machine type, the production process, available signals, existing controls, and the response that maintenance and production teams can realistically take. Specific hardware compatibility, detection performance, and integrations must be validated for the intended plant and equipment.
Which OEM Manufacturing Equipment Can Be Monitored?
The most useful starting point is a defined asset class and a clear operational question. Monitoring every machine in a plant is not necessary to establish value. A pilot can focus on a bottleneck asset, a recurring maintenance issue, or equipment whose condition may affect a safety-critical or quality-sensitive operation.
- Stamping and press lines: review vibration, motor current, hydraulic pressure, temperature, and cycle-related changes where these signals are available and appropriate.
- Conveyors and transfer systems: examine drive-motor vibration, gearbox temperature, current draw, speed, and unexpected changes in movement or cycle time.
- Robotic welding and body-in-white cells: assess robot drive or spindle condition, cooling systems, power supply behavior, and relevant cycle or fault records. Weld-quality inspection remains a separate verification task unless suitable inspection data is explicitly included.
- Paint-shop and finishing equipment: consider pump and fan vibration, motor temperature, pressure, flow, and environmental variables that influence equipment operation or process consistency.
- Final assembly equipment: monitor torque tools, lifts, fixtures, conveyors, and fastening or joining equipment using the signals and quality records appropriate to each asset.
Equipment condition monitoring should not be confused with vehicle-part traceability, personnel location, or finished-vehicle quality inspection. Those workflows may share equipment identifiers or production records, but each needs its own data, acceptance criteria, and validation method.
Measurement Plan: Capture Condition in Operating Context
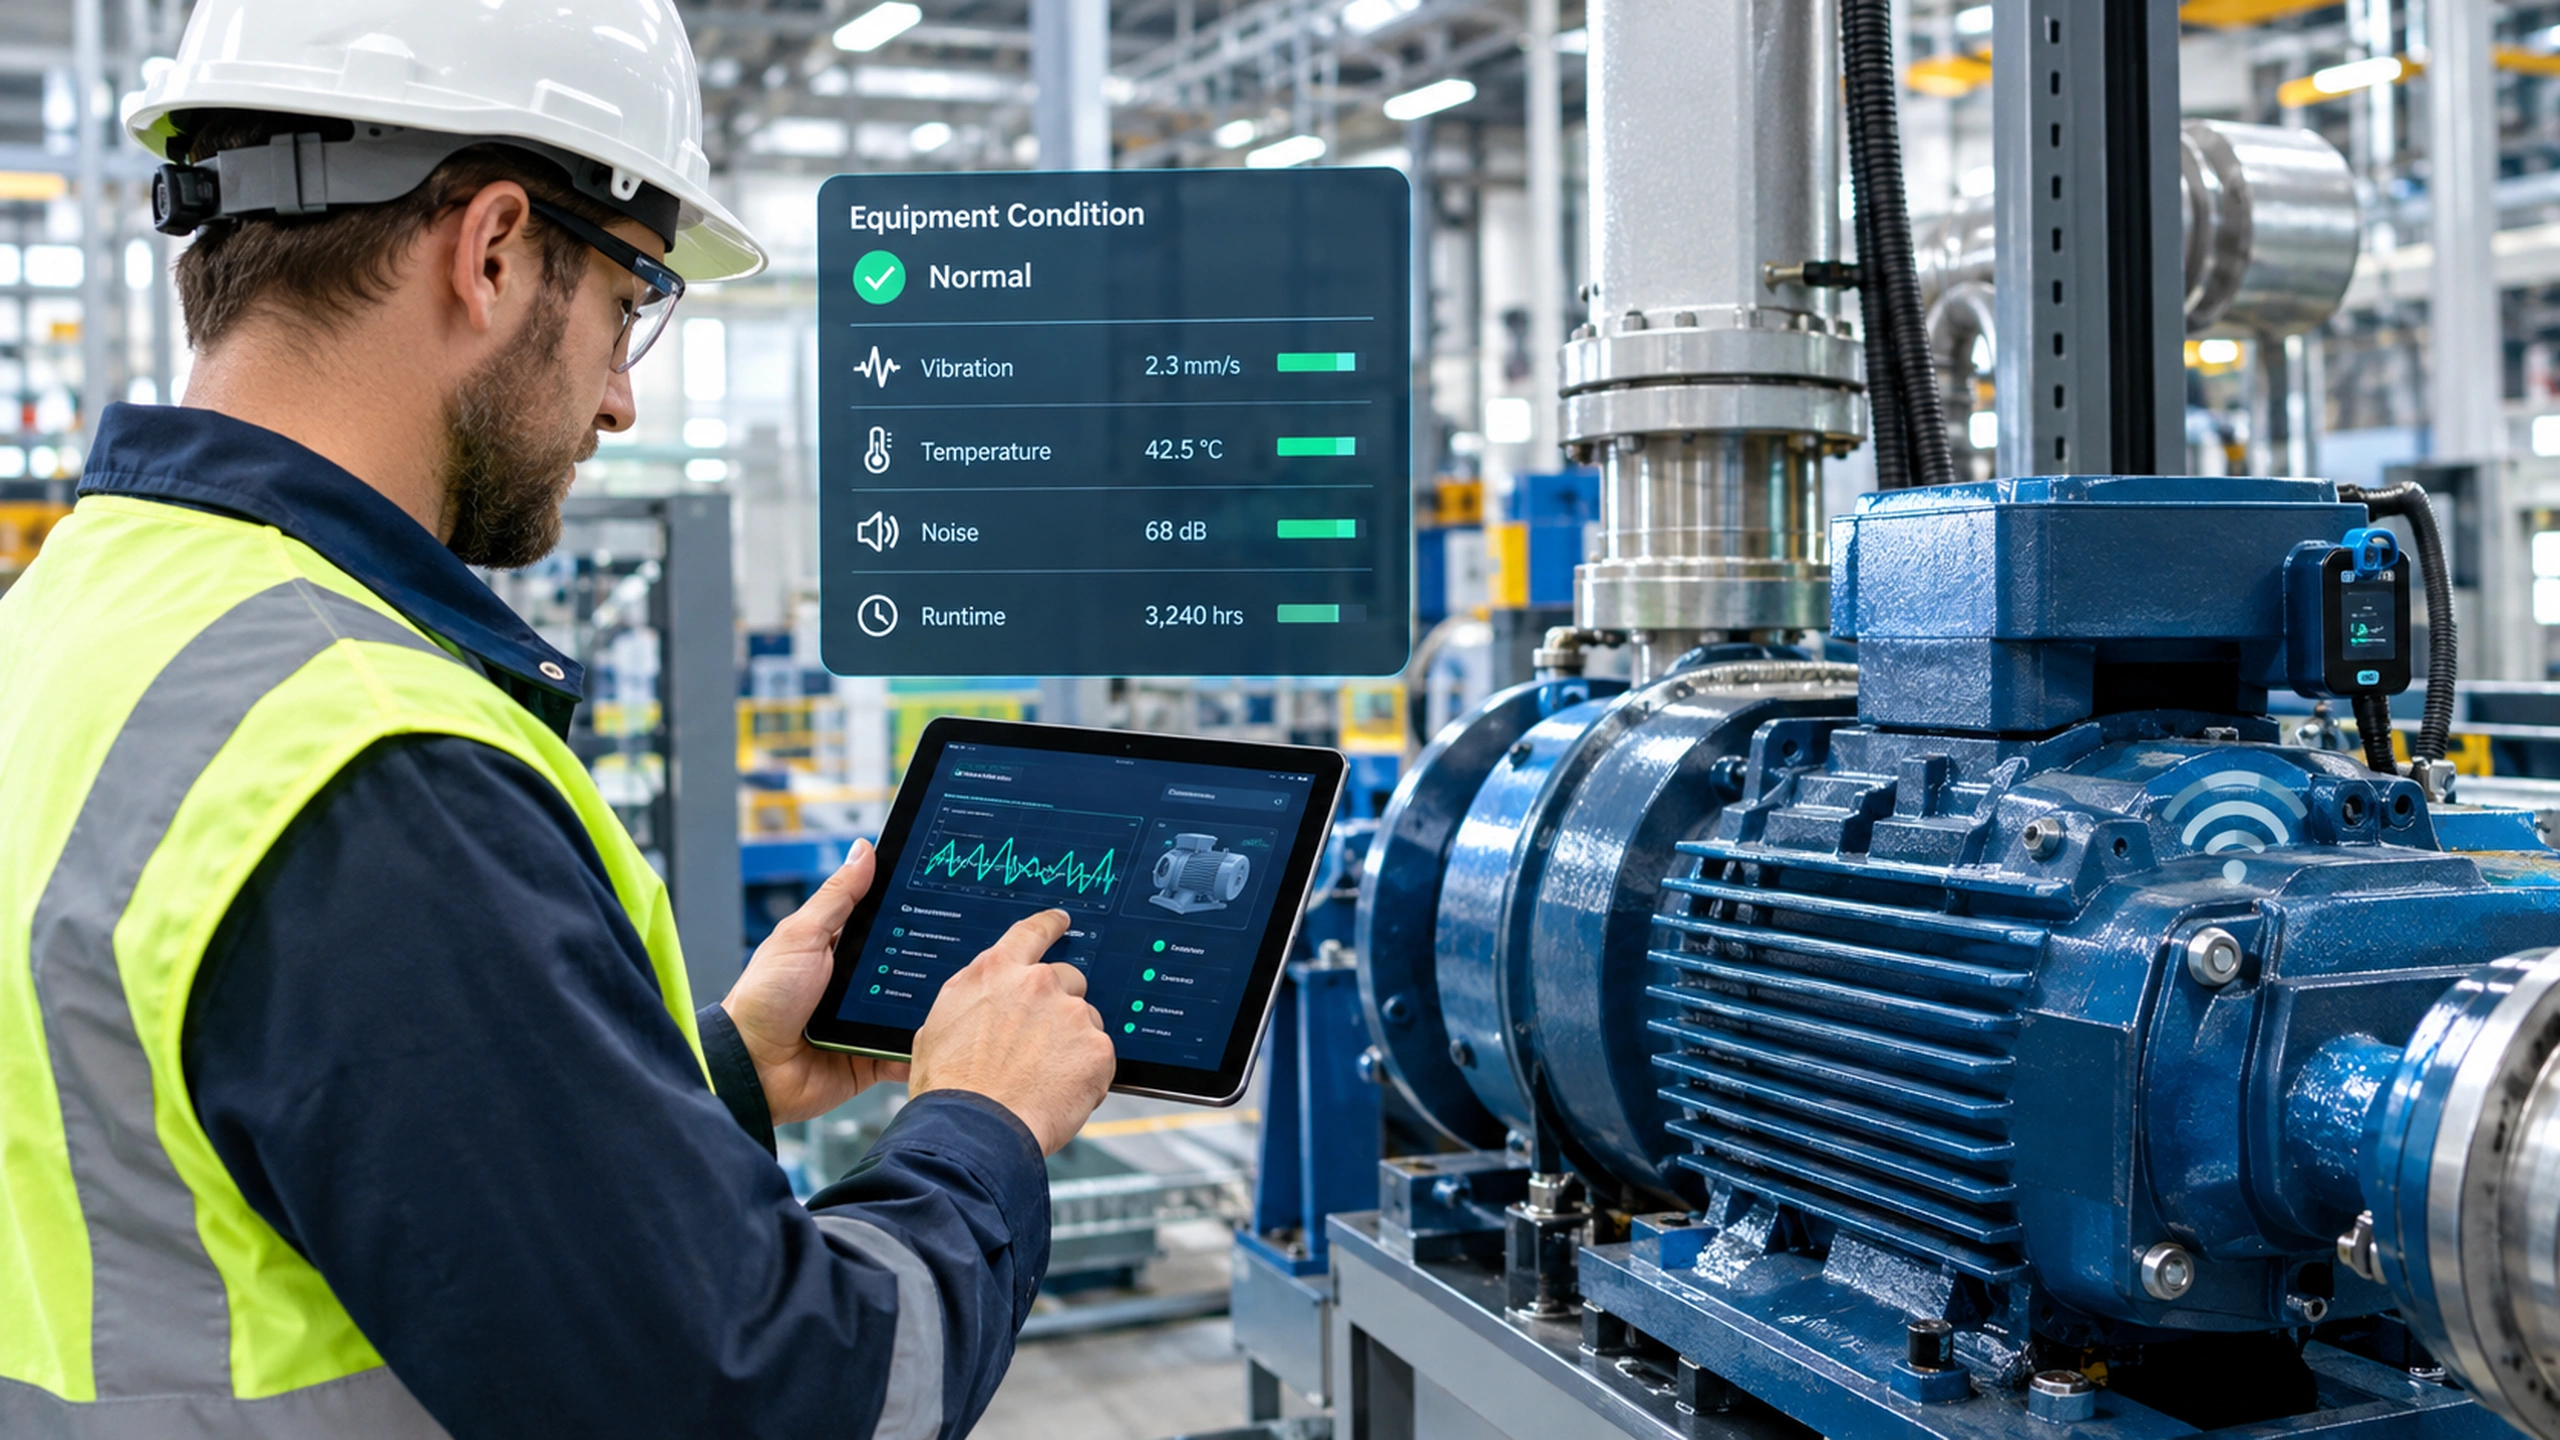
Measurements are useful only when the plant can interpret them in context. Vibration readings, for example, can change with machine speed, load, product mix, startup, or normal process variation. Temperature and current can vary by duty cycle. A measurement plan should identify the physical variable, measurement location, unit, sampling interval, operating mode, and calibration or verification requirements.
Depending on the equipment, relevant inputs may include vibration, temperature, pressure, flow, electrical current, acoustic signals, cycle counts, controller fault codes, runtime, and inspection images. Use only variables that have a defensible relationship to the condition being evaluated. A camera-based inspection may be suitable for visible defects or component presence, while vibration and temperature may be more appropriate for rotating equipment health.
The data record should associate each observation with a stable asset identifier, timestamp, operating state, measurement unit, source device, and quality flag. The system should identify missing, stale, duplicated, implausible, or out-of-range readings rather than treating every incoming value as reliable. Sensor placement, mounting, environmental protection, electromagnetic interference, network coverage, and maintenance access also affect data quality.
From Measurement to a Reviewed Maintenance Decision
A condition-monitoring workflow should make the path from observation to follow-up clear. Readings can be compared with approved limits, an established baseline, or a model that has been evaluated against representative operating data. A threshold rule may be sufficient for a known operating limit. AI-based anomaly detection may help identify combinations or patterns that are difficult to capture with a single threshold, but it needs representative data and ongoing review.
An abnormal result should not automatically be treated as a confirmed fault. The system can create an alert or review task with the asset identifier, timestamp, observed variables, operating mode, relevant trend, and reason for escalation. A maintenance or reliability engineer can assess the evidence, check controller alarms and production context, and decide whether to inspect the equipment, adjust a maintenance priority, or continue observing.
Where results are uncertain, data is stale, or the machine is operating outside the evaluated conditions, the workflow should state that limitation and route the case for human review. False alerts can create unnecessary work and encourage staff to ignore warnings. Missed abnormalities can be more consequential, particularly where a machine is a production bottleneck. Evaluation should therefore measure both useful detections and unwanted alerts.
Connect Findings with Maintenance and Production Records
Condition data becomes more actionable when it can be related to the maintenance and production records already used by the plant. Depending on the site, this may involve a computerized maintenance management system (CMMS), manufacturing execution system (MES), supervisory control and data acquisition (SCADA) system, programmable logic controller (PLC) records, or enterprise resource planning (ERP) data. These are possible integration targets, not a claim that a prebuilt connector is available.
A practical integration defines asset identifiers, event timestamps, units, severity, source, and the status of each finding. It should preserve the distinction between a raw measurement, an algorithm-generated anomaly, a maintenance assessment, a work order, and a verified repair result. Duplicate alerts need a grouping rule; delayed messages need a recovery process; and permissions should limit who can view, acknowledge, edit, or close a maintenance record.
Deployment may use edge processing near equipment, a customer-managed server, cloud services, or a combination, depending on latency, connectivity, data-governance, and support requirements. Any interface with machine controls requires a separate review of authorization, protective functions, and operating limits. A monitoring alert or software recommendation does not by itself authorize direct machine control.
Validation in an OEM Vehicle Plant
A pilot should test whether the monitoring method produces dependable information under real production conditions. Establish a baseline before deployment and select representative machines, shifts, products, load levels, startup and shutdown periods, and known operating variations. Include normal behavior as well as realistic abnormal conditions. Where safe and practical, compare alerts with inspection findings, maintenance records, controller fault history, and other independent evidence.
- Detection performance: calculate fault or abnormal-event recall using confirmed events as the denominator, and report missed events as well as detected ones.
- False-alert rate: count false alerts over a defined operating period, with a documented method for grouping repeated alerts from the same episode.
- Detection delay: measure elapsed time from a defined abnormal-condition onset to the first qualifying alert, only when the onset can be established reliably.
- Data quality: track missing or stale readings, device availability, calibration issues, and time-alignment problems.
- Maintenance workload: record inspection time, alert triage effort, work orders raised, findings confirmed, and alerts closed without action.
- Operational relevance: evaluate whether the information supports an actual maintenance or production decision. Do not infer avoided downtime or financial savings from detection results alone.
The evaluation should compare the candidate method with a credible existing practice, such as scheduled inspection or an approved threshold rule. Use matched operating scenarios where possible, document acceptance criteria before testing, and report limitations. If a simulation is used before a plant trial, label its data and results as simulated. A simulated result can help refine a pilot design, but it does not establish production performance.
Maintenance Response, Verification, and Continuous Review
After an alert is reviewed, the response should be recorded in a way that closes the loop. The responsible team may inspect a bearing, check lubrication, verify alignment, review a drive fault, or schedule a planned maintenance window, depending on the confirmed issue and plant procedures. Record the finding, action taken, parts or labor used where relevant, and the condition observed after the intervention.
A maintenance action should not be considered successful solely because a work order was closed. Where feasible, compare post-maintenance measurements with the prior condition and confirm whether the original abnormal pattern has changed. If the condition remains unresolved, route it for further investigation. Feedback from confirmed inspections and repairs can help engineers refine limits, improve labels, and evaluate whether an AI model remains useful as equipment, product mix, and operating practices change.
Any automatic adjustment or physical response must be separately authorized, bounded by engineering-approved limits, and verified using appropriate feedback. Equipment safety interlocks and other independent protective functions must remain in force. Human override, communications loss, rejected commands, and recovery behavior need to be addressed before any physical-control integration is considered.
Plan a Condition-Monitoring Application
OEMNex can discuss the equipment class, operating question, available measurements, maintenance workflow, and evaluation criteria for a proposed OEM vehicle manufacturing application. A useful first discussion identifies one or two target assets, the symptoms or events of interest, available historical records, current inspection practices, and the systems that would need to exchange information.
The next step is to define the monitoring boundary and decide what evidence a pilot must produce. Review measurement suitability, data quality, integration requirements, maintenance ownership, and acceptance criteria before making performance or return-on-investment claims.
Discuss your equipment monitoring application