
Edge, Cloud, and Server Deployment for OEM Vehicle Manufacturing
Deployment decisions determine where automotive manufacturing data is processed, where records are stored, and which systems remain available when a plant network or external connection is interrupted. For OEM vehicle manufacturing, the choice is rarely a simple edge-versus-cloud decision. Assembly lines, body shops, paint shops, powertrain operations, battery manufacturing, inspection stations, material handling, and plant utilities can have different timing, connectivity, data-volume, and availability requirements.
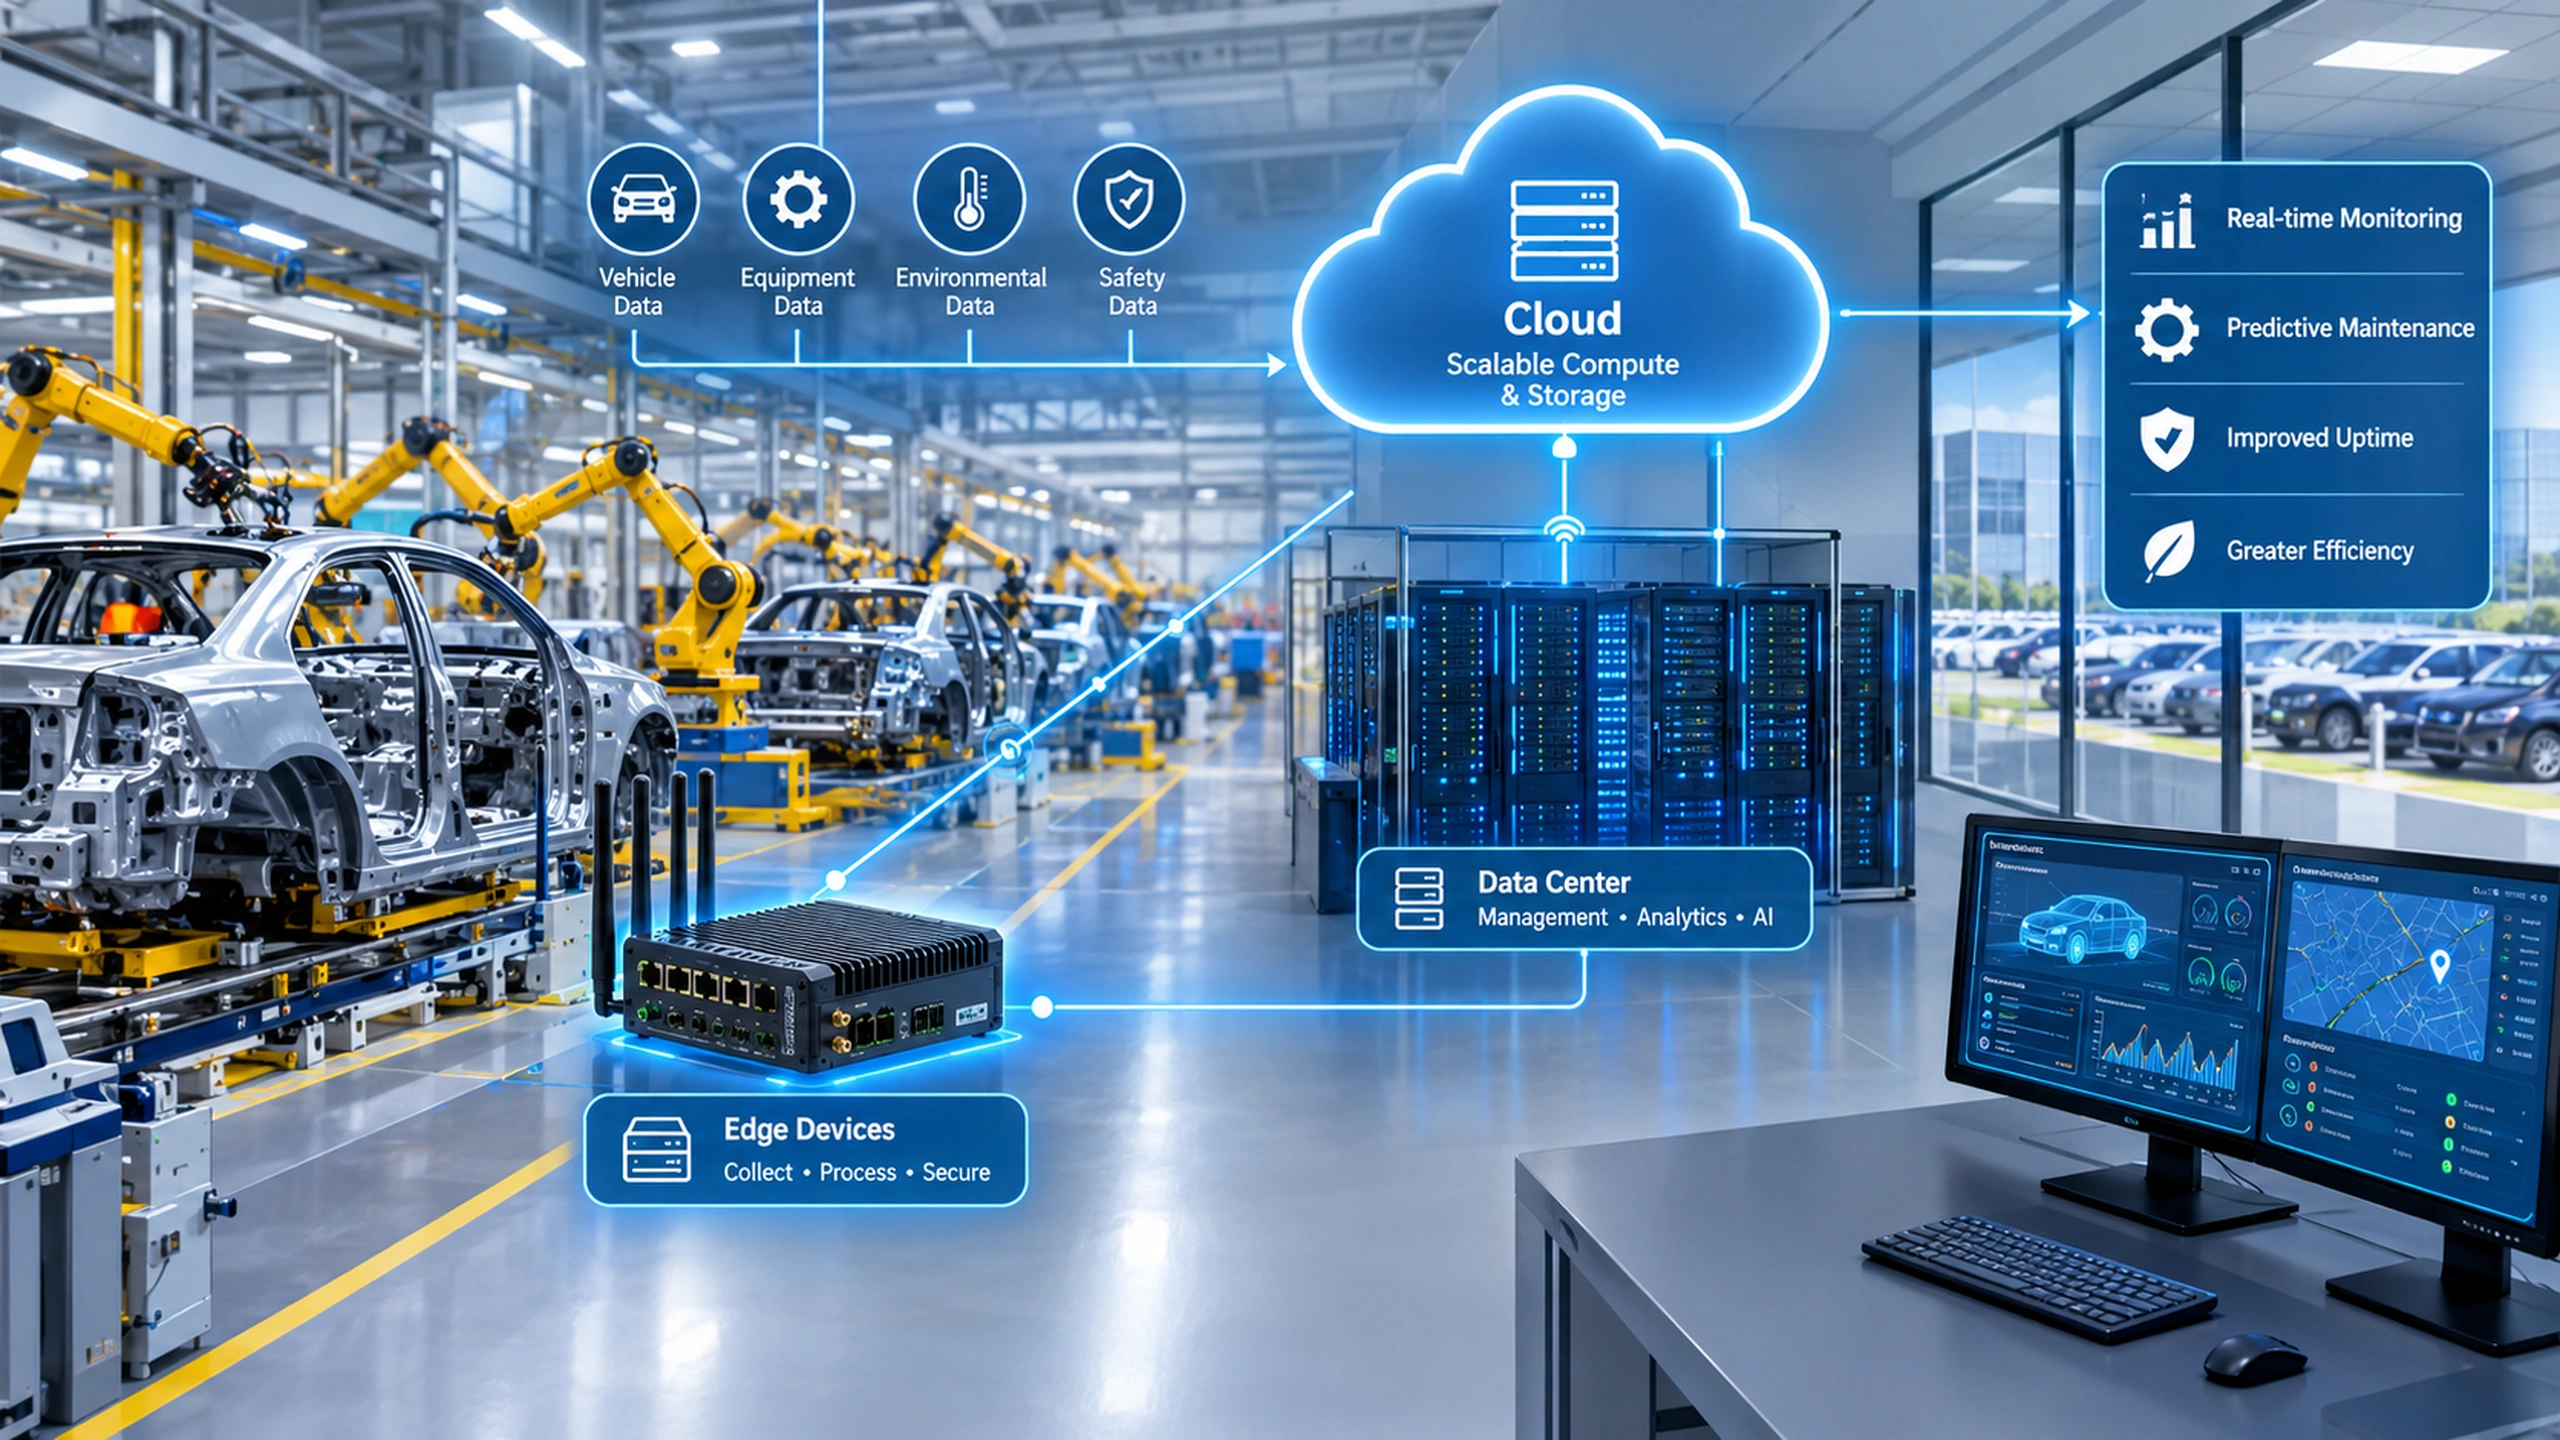
A practical deployment design separates functions by operational need. Field-edge devices can acquire sensor, machine, vision, identification, and vehicle data close to the equipment. On-site servers can provide plant-level services and retain selected data within the facility. Private hosting can place applications in a controlled computing environment, while cloud services can support centralized analytics, long-term storage, model development, fleet or plant comparisons, and access across locations. The appropriate arrangement depends on the workflow, not on a preference for one infrastructure model.
For engineers, plant IT teams, automation specialists, manufacturing execution system administrators, data engineers, and procurement teams, the important questions are where a function must run, what happens when connectivity is unavailable, who maintains the infrastructure, and how data moves into existing automotive manufacturing systems.
What Edge, Server, Private Hosting, and Cloud Mean in an Automotive Plant
Field-edge processing places computing close to production equipment or a defined plant area. An industrial computer or gateway can collect data from programmable logic controllers, sensors, cameras, radio-frequency identification readers, Bluetooth Low Energy devices, machine interfaces, and other connected equipment. Local processing can filter data, normalize timestamps, associate events with equipment identifiers, run selected AI inference, and forward only the records or features required by higher-level systems.
An on-site server provides computing and storage within the manufacturing facility. It can host plant applications, databases, integration services, dashboards, inference services, or other workloads that benefit from local availability. An on-site server may receive processed information from multiple production areas rather than connecting directly to every field device.
Private hosting places selected workloads in infrastructure managed for a specific organization or within a controlled private environment. It can be useful where the organization has established requirements for access control, network boundaries, data governance, application management, or centralized IT operations. The deployment model should be evaluated against actual operating and support requirements rather than treated as inherently more secure or more available.
Cloud services provide remotely operated computing and storage resources that can expand or contract according to workload needs. For automotive manufacturers with multiple plants, cloud services can support centralized historical data, cross-site analysis, model development, reporting, and shared software services. Cloud processing does not eliminate the need for local processing where production workflows require continued operation during connectivity loss or where response timing makes remote processing unsuitable.
How to Choose a Deployment Location
The first decision is the operational function, not the infrastructure brand. A condition-monitoring function for a robotic welding cell may need local data handling and rapid alert generation, while long-term analysis of welding trends across several plants may be better suited to centralized storage and analytics. A machine-vision inspection function may require local inference because high-resolution images are large and inspection decisions are tied to the production cycle. The retained images or extracted features can then be transferred for quality analysis, model improvement, or audit requirements.
Connectivity is equally important. A plant may have reliable internal networking while its connection to an external cloud service is temporarily unavailable. A deployment that assumes continuous external connectivity should define what happens during that condition. Local acquisition, buffering, alerting, and approved operational functions may continue, while nonessential synchronization can wait until the connection returns.
Data volume also affects the decision. High-frequency vibration streams, machine telemetry, industrial video, thermal imagery, and inspection images can create substantial traffic if every raw record is transmitted to a remote service. Edge processing can reduce the amount of data that crosses the plant boundary by extracting features, filtering redundant samples, or retaining only records required for a defined purpose. This should be balanced against the need to preserve raw evidence for quality investigations, model development, or regulatory and contractual requirements.
Maintenance capability should be treated as an engineering constraint. A plant that operates industrial computers, servers, networking equipment, and software locally needs personnel, procedures, spare capacity, patching practices, monitoring, backups, and recovery procedures. A cloud service changes the responsibility model but does not remove operational responsibility. Teams still need to manage identities, application configuration, data quality, interfaces, model versions, and business continuity.
Deployment Decision Matrix for OEM Vehicle Manufacturing
The following comparison provides a practical starting point. Actual deployment decisions should be validated against the specific production process, equipment interfaces, network design, cybersecurity controls, data policies, and support model.
- Field edge: Strong fit for time-sensitive equipment data acquisition, local filtering, machine-state detection, selected AI inference, protocol conversion, and operation that must tolerate temporary upstream connectivity loss.
- On-site server: Strong fit for plant-level applications, local databases, integration services, dashboards, centralized inference for several production areas, and workloads that need local availability.
- Private hosting: Strong fit when enterprise IT requires a controlled hosting arrangement for selected applications, data, or integration services and has defined ownership and support responsibilities.
- Cloud: Strong fit for centralized storage, cross-plant analytics, large-scale model development, consolidated reporting, remote application access, and workloads that benefit from elastic computing resources.
- Hybrid deployment: Strong fit when a manufacturing workflow needs local operation plus centralized analysis, long-term storage, model management, or cross-site comparison.
Connectivity and Response Needs
Functions should remain close to the production process when a delayed response could reduce the usefulness of the result. Examples include local equipment-state detection, immediate inspection classification, machine alarms, local data buffering, and gateway functions that connect plant equipment to higher-level software. This does not mean every decision must run at the edge. The appropriate boundary depends on the response requirement and the consequences of delay.
Data Handling and Retention
Determine whether the workload requires raw sensor readings, derived measurements, events, images, model outputs, or summarized records. Define how long each category must be retained, where it may be stored, who may access it, and how it will be associated with equipment, vehicle programs, production orders, stations, timestamps, and quality records.
Maintenance and Expansion
A deployment should have an explicit owner for hardware health, operating-system and application updates, backups, certificate or credential management, model versions, interface changes, and incident response. Expansion planning should consider additional production lines, new vehicle programs, higher sensor counts, additional cameras, increased data volume, and additional plants.
Hybrid Deployment Patterns for Vehicle Manufacturing
Hybrid deployment is often practical because an automotive plant contains workloads with different timing and data requirements. A representative design can place acquisition, protocol conversion, filtering, and selected AI inference at the edge. An on-site server can aggregate plant data, provide local dashboards, maintain operational databases, and coordinate integrations. Cloud services can receive selected historical records, quality evidence, model-training data, and cross-site metrics.
The boundary should be explicit. For example, an edge computer can receive vibration data from a motor-driven conveyor and calculate condition indicators locally. A plant server can retain the resulting time series and link it with equipment identity, maintenance records, and production context. A cloud service can compare condition indicators across plants or equipment populations and support model development. If the external connection fails, the local measurement and buffering functions can continue while synchronization waits for connectivity to return.
The same pattern can apply to machine vision. Cameras may send image streams to a local inference computer because transferring all raw video to the cloud would create unnecessary network load. The local system can return an inspection result to the production workflow, while selected images, defect classifications, and quality records can be forwarded for longer-term analysis. The exact split should be established through testing rather than assumed from a generic reference architecture.
What Happens During a Connectivity Outage?
Outage behavior should be designed before deployment. A useful system does not treat every lost connection as the same event. The design should classify functions according to whether they continue locally, buffer data for later transfer, degrade to a reduced function, require human intervention, or stop.
- Continue locally: equipment data acquisition, local state detection, selected inspection inference, local dashboards, and other functions designed for independent plant operation.
- Buffer and synchronize later: noncritical telemetry, historical measurements, selected images, event records, and other data that can tolerate delayed transfer.
- Degrade: functions that depend on remote analytics, centralized data, or services that are unavailable during the outage. The degraded state should be visible to responsible operators.
- Stop or require approval: functions that cannot safely or correctly continue without required external information, authorization, or a verified connection. The system should define the fallback procedure rather than silently proceeding.
Buffering requires more than a queue. The system should preserve timestamps, source identifiers, sequence information where needed, data-quality status, and enough context to reconcile delayed records. Duplicate events and partial transfers should be handled deliberately. When connectivity returns, the receiving system should be able to distinguish newly generated records from retransmitted records and reconcile them without corrupting production history.
Security and Operational Ownership
Edge, server, private-hosted, and cloud deployments create different administrative boundaries. The design should document which team controls each device, operating system, application, network segment, credential, interface, data store, backup, and software update. Automotive plants may also need to separate production networks from enterprise and external networks, with access granted according to defined operational responsibilities.
Security controls should cover device identity, authentication, least-privilege access, protected communications, network segmentation, logging, update procedures, vulnerability response, and recovery. When an AI or AIoT system produces an output that could influence physical equipment, additional controls are required around authorization, command interfaces, interlocks, human oversight, and verification. A cloud connection should not be treated as a direct control path to production equipment unless the complete control design has been evaluated and approved for that purpose.
Data ownership should also be explicit. Manufacturing data can include production parameters, machine conditions, inspection images, vehicle-program information, maintenance records, and operational events. The deployment plan should specify where these records reside, who can access them, how long they are retained, and how they are removed or transferred when systems change.
Example Deployment Selection for an Automotive Assembly Plant
Consider an OEM vehicle assembly plant evaluating AIoT-based condition monitoring for conveyor drives, robotic welding equipment, and selected inspection stations. The assumed requirements are local collection of vibration and temperature measurements, identification of the monitored equipment, local abnormal-condition detection, plant-level maintenance visibility, and centralized analysis of historical records across several facilities. The scenario does not assume a particular cloud provider, server product, network technology, or measured performance.
A reasonable conceptual arrangement would place sensor acquisition and initial processing at field-edge computers or gateways near the production equipment. These devices can associate readings with equipment identifiers, check data quality, calculate selected indicators, and buffer records during temporary upstream network interruptions. A plant server can provide local data services, maintenance dashboards, integration with the computerized maintenance management system (CMMS), and local access for plant engineering and maintenance personnel.
Selected condition records and quality evidence can be synchronized to a private or cloud environment for longer-term storage, cross-plant comparison, analytics, and model development. The centralized environment can support engineering teams that need to compare similar equipment across production lines or plants. The local plant system remains responsible for functions that require continued availability when the external service is unreachable.
The arrangement should be evaluated with representative equipment, normal production states, network interruptions, missing sensor data, delayed events, server restarts, and recovery from connectivity loss. Acceptance criteria can include data completeness, event reconciliation, alert usefulness, recovery behavior, maintenance effort, and the time required to restore normal synchronization. These measures provide evidence for the deployment decision without assuming that one infrastructure pattern is appropriate for every automotive plant.
Deployment Checklist for OEM Vehicle Manufacturing
Before selecting an edge, server, private-hosted, cloud, or hybrid arrangement, engineering and IT teams should document the following:
- Production workflow and equipment affected, including assembly stations, robots, conveyors, inspection systems, utilities, and material-handling equipment.
- Required response time and the operational consequence of delayed processing.
- Data sources, protocols, identifiers, timestamps, sampling rates, image volumes, and data-quality requirements.
- Functions that must remain available during loss of external connectivity.
- Data retention, access, ownership, backup, and recovery requirements.
- Responsibilities for edge hardware, on-site servers, applications, network services, cloud resources, updates, and incident response.
- Integration requirements for manufacturing execution systems (MES), enterprise resource planning (ERP), computerized maintenance management systems (CMMS), supervisory control and data acquisition (SCADA), quality systems, and other plant applications where applicable.
- Cybersecurity boundaries, authentication, authorization, logging, segmentation, and remote-access controls.
- Scaling requirements for additional production lines, vehicle programs, sensors, cameras, plants, users, and historical data.
- Pilot and acceptance tests covering normal operation, degraded connectivity, missing data, system restart, recovery, and reconciliation.
When a Hybrid Design Is the Practical Choice
A hybrid deployment is often appropriate when an OEM vehicle manufacturing workflow requires local responsiveness and availability but also benefits from centralized storage, analytics, and model management. The local layer can keep production-facing functions operating and reduce unnecessary data movement. Plant or private servers can provide controlled aggregation and integration. Cloud resources can support workloads that benefit from broader computing capacity or information shared across sites.
The important design principle is functional separation. Processing should be placed where its timing, connectivity, data, security, maintenance, and availability requirements can be met and tested. The final arrangement should be documented as an operational system with clear interfaces and recovery behavior, rather than as a generic edge-to-cloud diagram.
For OEM vehicle manufacturing teams, this approach makes deployment decisions easier to review with plant engineering, automation, IT, cybersecurity, quality, maintenance, and procurement stakeholders. It also provides a clear basis for a pilot: define the production problem, assign each function to an appropriate computing location, test normal and outage conditions, measure the results, and revise the deployment boundary before broader rollout.
Related Resources
- System Integration and Deployment: /technology-integration/system-integration-deployment/
- IoT Software: /technology-integration/iot-software/
- Physical AI and AIoT Engines Architecture: /physical-ai-aiot-engines-architecture/
- Cybersecurity and Physical Action Safeguards: /knowledge-center/cybersecurity-action-safeguards/